Sophos found that 53% of organizations fully recovered from ransomware within a week in 2025, while 18% took more than a month. The gap shows that recovery takes more than restoring clean data.
Ransomware does not only threaten data. Identity, networking, access policies, security rules, and cloud configurations can also be disrupted. If those configurations cannot be restored to a known-good state, data recovery alone may not restore operations.
This guide covers ransomware backup best practices for 2026, a step-by-step recovery process, realistic recovery timelines, and the role of configuration recovery alongside traditional backup.
TL;DR
- Ransomware recovery is treated as a backup problem, but 18% of organizations still take more than a month to recover – data alone isn’t the bottleneck.
- Restoring into the same account that got hit risks re-inheriting whatever let the attacker in; standard incident response calls for rebuilding in a clean, isolated account instead.
- Configuration – including IAM, networking, security policies, and cloud infrastructure – must also be restored in that clean environment. ControlMonkey makes this configuration layer recoverable from versioned, known-good snapshots.
- The 3-2-1-1-0 backup rule and a CISA/NIST-aligned response process remain foundational. ControlMonkey complements data backup by restoring the configuration required to operate.
- The compromised environment can remain quarantined for investigation while recovery proceeds in a clean environment.
What Is Ransomware Recovery?
Ransomware recovery is the process of restoring systems, data, and configuration to a trustworthy state after an attack. It differs from generic disaster recovery in one important way: it can’t assume the underlying environment is still trustworthy.
Disaster recovery covers hardware failure, regional outages, and human error. Its playbooks generally assume you’re recovering into infrastructure you still trust. Ransomware recovery can’t make that assumption, because the attacker had access to that same environment. The environment itself has to be verified or rebuilt, not just the data sitting in it.
Ransomware Recovery vs. Disaster Recovery vs. Backup Restore
| Backup Restore | Disaster Recovery | Ransomware Recovery | |
|---|---|---|---|
| Trigger | Data loss or corruption | Infrastructure or site failure | Malicious compromise |
| Scope | Specific files or datasets | Systems and infrastructure | Data, configuration, and environment trust |
| Environment assumption | Trusted | Trusted | Compromised – must be verified or rebuilt |
| “Done” looks like | Files are back | Systems are back online | Data, configuration, and environment are all verified clean |
Why Restoring Files Isn’t Enough
Most incident-response guidance leaves teams with a familiar list of chores after data comes back: re-validate ACLs, firewall rules, and security groups. Rotate every credential, especially admin and service accounts. Recheck configuration before anything rejoins production.
That list is the manual-rebuild tax. It’s the work left over once “the data is back” stops being true and “the environment is safe to use” hasn’t started yet. Closing that gap means treating the last known-good state – infrastructure-as-code state, IAM policies, network rules, resource dependencies – as something that gets recovered on its own track, with the same rigor as the data.
This is the disaster recovery gap the ControlMonkey Cyber Resilience Platform closes. Traditional data backup stops at the data layer; ControlMonkey continuously captures and versions the configuration layer underneath it, so the manual-rebuild tax doesn’t fall on your team during an actual incident.
How Does Ransomware Data Recovery Work?
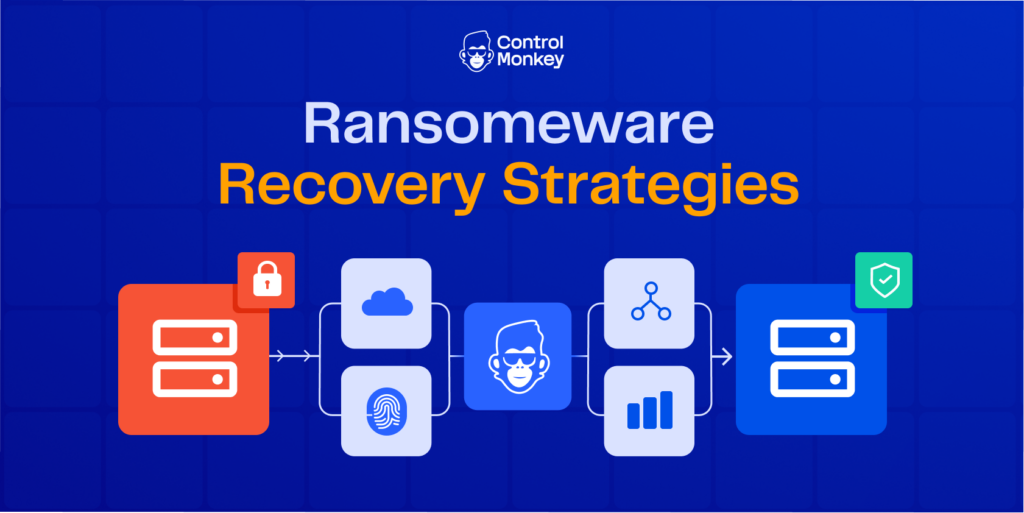
Ransomware data recovery runs as two parallel tracks: restoring data from a verified clean point, and rebuilding configuration from a known-good state, into a clean account. These converge into a validated environment before operations resume.
- Detect and contain the attack. Isolate affected systems from the network before anything else.
- Preserve evidence before wiping or restoring anything. Ransom notes, logs, EDR alerts, and the list of potentially compromised accounts matter for forensics, legal, and insurance – capture them before you touch anything.
- Assess blast radius across both data and configuration. Which systems were touched? Did the attacker reach IAM, network rules, or IaC pipelines, not just file storage?
- Restore data from a clean, verified point. An unverified backup isn’t a recovery point – it’s just a copy.
- Rebuild the environment in a clean, isolated account from a known-good configuration, in parallel with the data restore, not afterward.
- Validate the combined result as a known-good state before resuming production traffic.
Step 5 matters as much as step 4. A data restore landing in an environment with drifted or tampered configuration doesn’t give you back a working system – it gives you back correct data sitting inside a broken one.
Ransomware Backup Best Practices
Backup discipline is still the foundation everything else sits on. Configuration recovery only matters if the underlying data is recoverable in the first place.
The 3-2-1 Backup Rule for Ransomware – and Its 2026 Update
The classic 3-2-1 rule – three copies of your data, on two media types, with one copy offsite – is CISA-endorsed baseline practice. But ransomware that specifically targets connected backup repositories has pushed most current guidance toward an extended version: 3-2-1-1-0 – three copies, two media types, one offsite, one immutable or air-gapped, and zero recovery errors confirmed through regular testing.
That extra “1” and “0” exist because ransomware operators know backups stand between them and a payout. An immutable or air-gapped copy is the one an attacker with valid credentials still can’t alter or delete.
The 3-2-1-1-0 rule protects your data copies. It says nothing about the configuration that has to sit on top of that data to make it usable again, or about which account you restore it into.
Immutable and Versioned Backups
Immutability shouldn’t stop at data storage. Configuration deserves the same treatment: versioned snapshots – tamper-evident records of what your infrastructure looked like at a known-good point in time, ready to rebuild from.
Back Up Configuration, Not Just Data
This is where most backup guidance stops short. When only data is restored, here’s what’s typically still broken: IAM policies and role bindings, network ACLs and security group rules, Terraform or other IaC state, and the dependency relationships between resources. Not just data – configuration has to be backed up, versioned, and restorable on its own track.
Test and Validate Recovery Readiness Before You Need It
An untested recovery plan is a hypothesis, not a plan. Recovery drills should validate a full rebuild into a clean account – data and configuration together – not just confirm a data restore completes. A tested backup that boots into a misconfigured environment isn’t a tested recovery.
Ransomware Backup Strategy: Building a Resilient Architecture
Individual best practices only add up to a strategy once they’re organized around how an attack actually spreads.
Segment recovery by blast radius.
Design your recovery scope around what a single compromised credential can reach – not around what’s simplest to back up. If one compromised service account can touch every environment, your blast radius is your entire infrastructure, regardless of how granular your backup schedule looks on paper.
Choose automated recovery vs. controlled recovery deliberately.
Automated recovery is faster and reduces manual error under pressure. Controlled recovery – requiring human sign-off before systems come back online – matters more in regulated environments, where a wrong or premature restore costs more than the time it saves.
Treat configuration governance as prevention, not just recovery.
Ransomware and attacker tampering often show up first as an unauthorized or malicious configuration change – a modified IAM policy, a disabled security control – before encryption ever starts. Drift detection that flags unexpected configuration changes functions as an early-warning signal for ransomware activity, not just a hygiene practice. Read more on building a resilient cloud disaster recovery strategy.
How to Recover From a Ransomware Attack (Step-by-Step)
Isolate first, preserve evidence, determine true scope, then rebuild into a clean environment before validating and resuming operations. This is the shape of the process CISA’s own #StopRansomware Guide recommends, and it’s the process real incident response teams actually follow.
- Isolate affected systems immediately – disconnect them from the network before anything else.
- Preserve evidence before wiping or restoring. This protects your ability to determine how the attacker got in and supports legal, insurance, and forensic requirements later.
- Engage incident response and legal/compliance stakeholders. Notification obligations and insurance requirements start the moment an incident is confirmed.
- Determine the true blast radius – across data and configuration – before restoring anything. Restoring blind extends downtime; it doesn’t shorten it.
- Rebuild the environment in a clean, isolated account from a known-good configuration, restoring data into that same clean environment.
- Validate integrity before reconnecting to production. Confirm the environment is behaviorally normal, not just technically “restored.”
- Run a post-incident review and update the runbook. Every recovery surfaces gaps the last one didn’t.
For the official playbook this process draws from, see CISA’s #StopRansomware Guide and NIST IR 8374 Rev. 1, finalized in June 2026 and aligned to CSF 2.0.
Data Recovery and Configuration Recovery Have to Finish Together
Restoring data does not restore operations. A recovery isn’t done when the data is back online – it’s done when a clean environment is back to a known-good, operable state, data and configuration verified together. Treating those as sequential steps is exactly what stretches a recovery from days into weeks.
Should You Pay the Ransom?
Standard guidance, including from CISA, is to avoid paying when possible: payment doesn’t guarantee full data recovery, and it funds further attacks. Organizations under the least pressure to even consider it are the ones with a recovery process that reliably works without needing the attacker’s cooperation.
Recover Into a Clean Account, Not the One That Got Hit
Once an environment is compromised, restoring directly back into it carries real risk. A persisted credential, a backdoor account, or a still-tampered policy can all survive a data restore untouched. Standard incident-response practice calls for standing up a clean, isolated environment – a “clean room” – and bringing services back online there, rather than restoring in place.
The clean account needs more than empty infrastructure with clean data dropped into it. It needs the known-good configuration rebuilt inside it – IAM policies, network rules, IaC state, resource dependencies – all replicated from a verified point before the attack. This is where configuration recovery does its actual work: not restoring configuration in place inside the compromised account, but replicating a known-good configuration into a new, trusted one.
The original account doesn’t get torn down. It stays quarantined – preserved for forensics, legal review, and insurance requirements, exactly as it was at the point of compromise. Recovery moves forward in the clean account while the compromised one sits untouched as evidence.
How Long Does It Take to Recover From Ransomware?
Recovery timelines vary widely: Sophos’s 2025 survey found 53% of organizations fully recovered within a week, while 18% took more than a month. The gap between those two groups usually comes down to whether configuration had to be rebuilt by hand.
What Extends Recovery Time
Manual configuration rebuilds, undocumented system dependencies, re-validating ACLs and firewall rules one by one, standing up a clean environment with no known-good reference to work from, and uncertainty about how far the attack actually spread.
What Shortens It
Immutable, versioned recovery points for both data and configuration; a rebuild process that replicates known-good configuration into a clean account automatically instead of manually; and runbooks tested against the full stack, not just the data layer.
Ransomware Protection and Recovery: The Compliance Angle
Ransomware readiness isn’t purely an IT concern – it’s a board-level and regulatory one. Frameworks like the EU’s Digital Operational Resilience Act (DORA) and the NIS2 Directive place explicit requirements on operational resilience and recovery capability for regulated entities, and both are increasingly referenced in enterprise security reviews even outside the EU.
Recovery readiness – documented, auditable processes for how recovery decisions get made, backed by evidence those processes actually work when tested – is what turns “we have a recovery plan” into something a CISO or auditor can verify. Keeping the compromised account quarantined and demonstrating a repeatable clean-room rebuild process is a compliance and audit asset in its own right, not just good incident response.

Explore how ControlMonkey’s Cyber Resilience Platform helps support recovery readiness and alignment with DORA, NIS2, SOC 2, and NIST CSF 2.0.
How ControlMonkey Powers Configuration Recovery Into a Clean Account
Everything in this article points to the same conclusion: ransomware recovery succeeds or fails on configuration, not just data. The ControlMonkey Cyber Resilience Platform is built around that gap – it closes the disaster recovery gap left by traditional data backup through four stages:
Discover → Snapshot → Recover → Review & Govern.
ControlMonkey continuously discovers cloud and SaaS configuration, captures versioned recovery points, and restores individual resources and configurations from known-good states. Broader environment recovery is available where verified for the specific provider and use case – replicating known-good configuration into a new, clean account rather than restoring in place inside the one that was compromised, while the original stays quarantined for forensics, legal, and insurance.
Block, one of ControlMonkey’s customers, put this to work across a multi-cloud environment: 80% faster recovery effort, 100% multi-cloud infrastructure recoverability, and full production coverage in roughly two weeks. In their words: “ControlMonkey helped us achieve the level of resilience we envisioned. 100% of our multi-cloud infrastructure is recoverable.”
A 30-min meeting will save your team 1000s of hours
A 30-min meeting will save your team 1000s of hours
Author